How to Keep Your RAG System Up to Date When Documents Change
Published on September 22, 2026
Use AI to summarize this article
 ChatGPT
 Claude
 Grok
 Perplexity
 GoogleAI
A company updates its refund policy from 30 days to 14 days. The new policy is already live on its website, but its AI assistant continues telling customers that they have 30 days to request a refund.
The AI model is working. The problem is that the RAG system is still searching an old copy of the policy.
This can happen with product documents, support articles, pricing information, internal policies, contracts, and other business data. A document changes in the original system, but the information stored for AI search does not change with it.
For a RAG system that answers questions using company information, keeping documents up to date is part of making the system reliable.
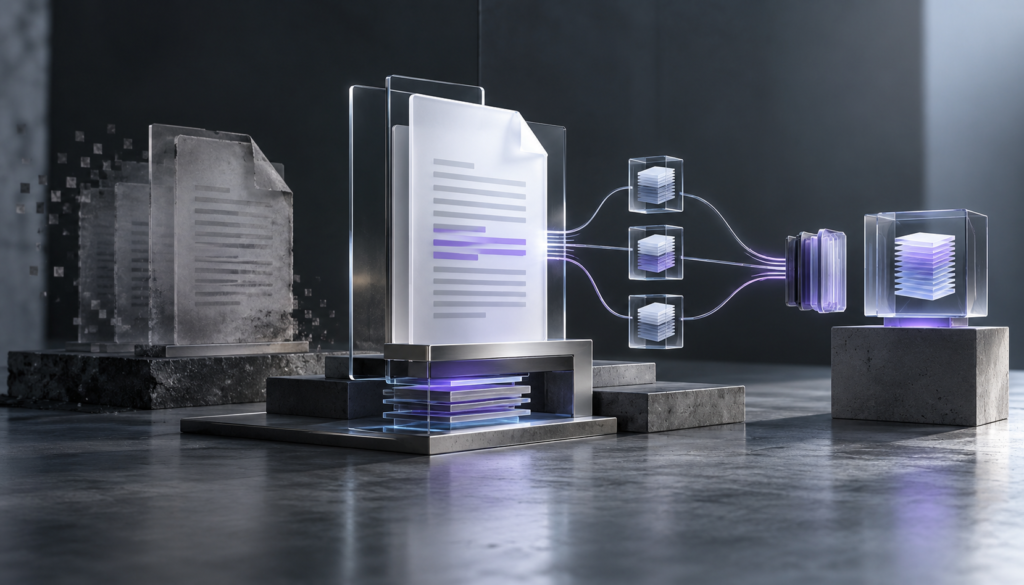
In this article, we will explain how to detect document changes, update embeddings, remove old information, handle deleted documents, and make sure the AI retrieves the correct version. We will also look at how to build this process without reading and processing every document again whenever one file changes.
Why does a RAG system give answers from old documents?
RAG stands for Retrieval Augmented Generation. It is a way to give an AI model information from external sources before the model answers a question.
In a common RAG system, documents are read, divided into smaller pieces, and converted into embeddings. An embedding is a list of numbers that represents the meaning of a piece of text.
These embeddings are stored in a vector database. When someone asks a question, the application searches that database for relevant information and sends the results to the AI model.
The important detail is that the vector database does not automatically know when the original document changes.
Imagine this situation:
- A company uploads a refund policy that allows returns within 30 days.
- The RAG system reads the policy and stores its embeddings.
- Two months later, the company changes the policy to 14 days.
- The original document is updated, but the RAG system is not.
- A customer asks how long they have to return a product.
- The AI retrieves the old policy and answers 30 days.
The answer may look correct because it is based on a real document. But it is based on the wrong version.
Changing the prompt or using a more capable model does not fix this problem. The application needs to keep the information used for retrieval in sync with the original source.
If you are new to retrieval, our article on LLM vs RAG vs Agent Systems explains how RAG uses external information and when it makes sense to use it.
What actually needs to change when a document is updated?
Updating a RAG system is not always as simple as replacing one file in storage.
A document may have several copies of its information across the application.
- The original file or record in the source system
- The text extracted from the document
- The smaller pieces of text created for retrieval
- The embeddings stored in the vector database
- The document details stored with those embeddings
- Search results or AI answers saved in a cache
A cache is a temporary place where an application keeps results so it can use them again without repeating the same work.
If the original file changes but the old embeddings remain in the vector database, the AI may continue retrieving outdated information.
If the embeddings are updated but a search cache still contains the previous results, users may still receive information from the old document.
If a document is removed from the source system but its embeddings remain searchable, the AI may continue using a document that should no longer be available.
This means a reliable RAG update process must track the document from its original source all the way to the information the AI is allowed to retrieve.
Start by keeping a record of every document
Before building automatic document updates, the application needs a way to identify each document and track its current state.
Do not use only the filename as the document ID. Different users may upload files with the same name, and a document can be renamed without its content changing.
Instead, assign each document a stable ID that remains the same when its contents are updated.
For example, a document record could contain the following information.
| Field | What it tells us |
|---|---|
| Document ID | The permanent ID used to identify the document. |
| Source ID | The original file or record in the source system. |
| Customer ID | Which customer or company owns the document. |
| Source version | Which version of the original document is being processed. |
| Content hash | Whether the document content has changed. |
| Indexed version | Which version is currently available for AI search. |
| Last updated | When the original document was last changed. |
| Last indexed | When the RAG system last finished processing it. |
| Status | Whether the document is active, being updated, deleted, or has failed processing. |
The source version and indexed version are especially important.
For example, the source system may contain version 8 of a policy, while the vector database still contains version 7.
The application can use this information to identify documents that need to be processed again.
It can also prevent an older processing job from replacing a newer version by mistake.
How to detect when a document changes
The first part of keeping RAG data up to date is finding out when something changes in the original source.
There are three common ways to do this.
1. Receive an event when a document changes
If the source system supports events or webhooks, it can notify your application whenever a document is created, updated, or deleted.
For example, imagine a company stores its support articles in a content management system.
When an employee publishes an updated article, the content management system sends an event to the RAG application.
The event might contain the document ID, the type of change, and the new version.
{
  "event": "document.updated",
  "document_id": "refund_policy_102",
  "source_version": 8,
  "customer_id": "company_25"
}
The application can then retrieve the updated document and begin processing it.
Where possible, the event should identify the document rather than include the entire document content. The processing service can fetch the current version from the original source using its own approved access.
This also allows the service to check whether the document has changed again since the event was created.
2. Check the source for changes at regular times
Not every system supports webhooks.
For those systems, a scheduled process can check for new, updated, and deleted documents.
For example, the application could check an internal document system every five minutes and compare the latest document versions with the records stored in its database.
If a document has a newer version, the application creates a processing job.
The schedule depends on the business. A system that answers questions about frequently changing prices may need faster updates than one that searches archived technical manuals.
Checking the source at regular times is often called polling.
3. Read changes directly from the source database
If the documents are stored in a database, the application may be able to read its change history.
Some databases can record when a row is created, updated, or deleted. This is useful because the application can identify what changed without reading the entire database again.
Microsoft Azure AI Search supports this approach for supported Azure SQL configurations. Its Azure SQL indexing documentation explains how database change tracking can be used to find new, changed, and deleted records.
The right method depends on where your source documents live and which features that system supports.
Webhooks can provide quick updates. Scheduled checks provide another way to find changes. Database change tracking can be useful when the source already keeps a reliable record of updates.
For important systems, do not depend on a webhook alone. Events can be missed if the receiving service is unavailable. A regular check against the original source can help find changes that were not processed.
How to update embeddings when a document changes
Once the application knows that a document has changed, it needs to update the information used for retrieval.
Consider the refund policy example again.
Version 7 says that customers can request a refund within 30 days. Version 8 changes that period to 14 days.
The application should not create another searchable copy of the policy while leaving the old version available.
That could cause both versions to appear in search results.
Instead, the update process should prepare the new version and make sure the old version can no longer be used after the update is published.
Step 1. Retrieve the latest document
When the update job starts, it should fetch the current document from the original source.
Do not assume that the version mentioned in an earlier event is still the latest version.
A document may have been edited again while the first update was waiting in the queue.
The application should record which source version it is processing and check that the document has not been replaced by a newer version before publishing the result.
Step 2. Check whether the content really changed
A document can be updated without its text changing.
For example, an employee might change its filename, folder, owner, or access permissions.
To identify changes to the content itself, the application can generate a content hash.
A content hash is a value calculated from the document’s content. If the content changes, its hash will normally change too.
For documents, the hash should be based on the content that is actually used for extraction or indexing, after applying a consistent method of reading and cleaning it.
If the content hash has not changed, the system may be able to skip creating new embeddings.
However, it must still check whether the document’s permissions or other important information have changed.
A document becoming private is not a reason to rebuild its embeddings. It is a reason to update its access rules immediately.
Step 3. Read the text and divide it into chunks
If the content has changed, the system reads the new document and divides it into smaller pieces of text, often called chunks.
These chunks should keep enough surrounding information to make sense when they are retrieved later.
For example, a refund policy might contain separate sections about eligibility, refund periods, damaged products, and payment methods.
Keeping related information together makes it easier for the AI to retrieve a useful section instead of a small piece of text without its meaning.
When a document changes, the system should check whether the previous chunk boundaries are still valid.
If a paragraph is added near the beginning of a document, chunks created from fixed text positions may shift throughout the file.
That means changing one paragraph can sometimes require processing several chunks again.
For documents with clear sections, stable section IDs can make it easier to identify which parts have changed. But this only works when the document format and parsing process support it reliably.
Step 4. Generate embeddings for the new content
After preparing the updated chunks, the application creates embeddings for the chunks that need to be indexed.
Each chunk should be stored with information that identifies where it came from.
For example:
{
  "chunk_id": "refund_policy_102_v8_01",
  "document_id": "refund_policy_102",
  "source_version": 8,
  "customer_id": "company_25",
  "section": "Refund period",
  "text": "Customers can request a refund within 14 days."
}
The example above shows the text and document details. The embedding itself would also be stored in the format required by the selected vector database.
Including the document ID and version makes it possible to identify which chunks belong to the same document and which version they represent.
If only a few documents have changed, there is no reason to regenerate embeddings for every other document in the knowledge base.
This approach is called incremental indexing.
Amazon Bedrock Knowledge Bases supports incremental syncing for supported data sources. Its knowledge base sync documentation explains how added, changed, and deleted documents are handled during a sync.
Step 5. Check that the new version is ready
Before making the new version available to users, the application should confirm that processing finished correctly.
For example, it should check whether:
- The latest document was retrieved successfully.
- Its text was extracted without a processing error.
- The required chunks were created.
- The new embeddings were stored successfully.
- The expected chunks are available for retrieval.
- The new document version is still the latest version in the source system.
Only after these checks should the application mark the new version as ready for use.
This matters because indexing can take time. A database write completing does not always mean the new content is immediately available through every search service.
How to replace the old document without mixing both versions
This is an important part of the implementation.
Imagine that the RAG system contains five chunks from version 7 of a policy. The updated version produces six chunks.
If the application simply uploads the six new chunks, the database may now contain eleven searchable chunks from the same document.
Some results may come from version 7 and others from version 8.
The AI might receive both refund periods in the same request.
There are two practical ways to manage document replacement.
Option 1. Remove the old chunks before adding the new ones
This is simple to understand and may be enough for a small system.
The application identifies every chunk belonging to the old document version, removes those chunks, and adds the new version.
The limitation is that the document may temporarily be unavailable while the new embeddings are being created and indexed.
If processing fails after the old chunks have been deleted, the application has no searchable copy until the problem is fixed.
Option 2. Prepare the new version before making it active
For a system where documents must remain available during updates, you can prepare a new version separately.
The process works like this:
- Keep the current document version available while the update is being prepared.
- Generate and store the new chunks with the new version number.
- Check that the new chunks have been indexed successfully.
- Mark the new version as the active version in the application’s database.
- Make sure retrieval accepts only chunks belonging to the active version.
- Remove the old chunks after the new version is active.
The key is step 5.
Storing a new version does not automatically stop the search service from returning the old version. Your application must enforce which version can be used.
For example, when a search result is returned, the application can compare its document ID and version with the current version stored in the main database.
If the result belongs to an old version, the application should remove it before sending context to the AI model.
Where your search service supports the required filtering, use it during retrieval as well. Filtering results only after search may leave too few useful matches, so the retrieval process must also handle that case.
There is one more important case. If a newer policy is already live in the source system but its embeddings are not ready, the application should not continue presenting the previous policy as current.
For information that must always be current, the safer response is to temporarily exclude that document from retrieval or get the latest information directly from the original source.
A vector database and a separate application database do not automatically update together as one operation. Your application needs to manage that process.
What happens when a document is deleted?
Deleting documents needs its own workflow.
If a company removes a policy from its website, deleting the original file does not guarantee that the old policy disappears from its RAG system.
The vector database may still contain the document’s chunks and embeddings.
This is a known issue in search systems. Microsoft explains in its Azure AI Search documentation on changed and deleted files that detecting an updated file and detecting a deleted file are separate problems.
For a custom RAG system, a document deletion process should do the following:
- Record that the original document has been deleted.
- Stop the document from being used in new AI requests immediately.
- Find every chunk and embedding that belongs to the document.
- Remove those records from the vector database.
- Clear any saved search results that contain the deleted document.
- Confirm that the document can no longer be retrieved.
The application should not wait for the vector database deletion to finish before blocking access to a document that has already been removed or made private.
A document status stored in the main application database can help enforce this rule.
If the document is marked as deleted, the retrieval layer should reject its results even if the old embeddings have not yet been removed.
For systems with strict data removal requirements, also review the retention and deletion rules of the selected storage, search, backup, and AI providers.
How to handle a document that is updated several times
Now consider a more difficult situation.
An employee changes a policy three times within a few minutes.
Version 8 is published. A processing job starts.
Before it finishes, version 9 is published. Another job starts.
Then version 10 is published.
If all three jobs run at the same time, the application might finish processing version 10 before version 8.
Without a version check, the older job could later overwrite the result of the newer job.
The document would become outdated again even though the latest version had already been processed.
To prevent this, the application should track the source version of every processing job.
Before publishing an update, the worker must check that the version it processed is still the version that should be active.
To keep a RAG system up to date, your application needs to detect when documents are added, changed, or deleted. It should then update the relevant embeddings, remove old information, and check that the AI retrieves the current document version.
Yes, if the document content used for search has changed, the affected embeddings may need to be updated. However, if only the filename or access permissions change, you may not need new embeddings. The system should still update the document details and permissions.
You can use incremental indexing. This means tracking document changes and processing only the documents or sections that need an update. Documents that have not changed can keep their existing embeddings.
The AI may retrieve both old and new information from the same document. This can lead to incorrect or conflicting answers. A reliable update process should make sure only the correct document version is available for retrieval.
When a document is deleted, the application should immediately stop using it for new AI requests. It should then remove the document's chunks and embeddings from the vector database, clear any related cached results, and confirm that the deleted information can no longer be retrieved.
It depends on how often the source information changes and how quickly users need the latest information. A system using pricing or policy documents may need updates within minutes, while a system using older technical manuals may need updates less often. The update schedule should match the needs of the business.
Yes. Your application can use webhooks, scheduled checks, or database change tracking to detect document updates. A background process can then read the latest content, update the embeddings, and make the new version available for AI search.
Compare the version stored in the original document source with the version available in the RAG system. You should also test whether the AI retrieves updated information after a document changes and whether deleted documents are no longer available. Checking the retrieved documents directly is more reliable than checking only the final AI answer.